Back to Home
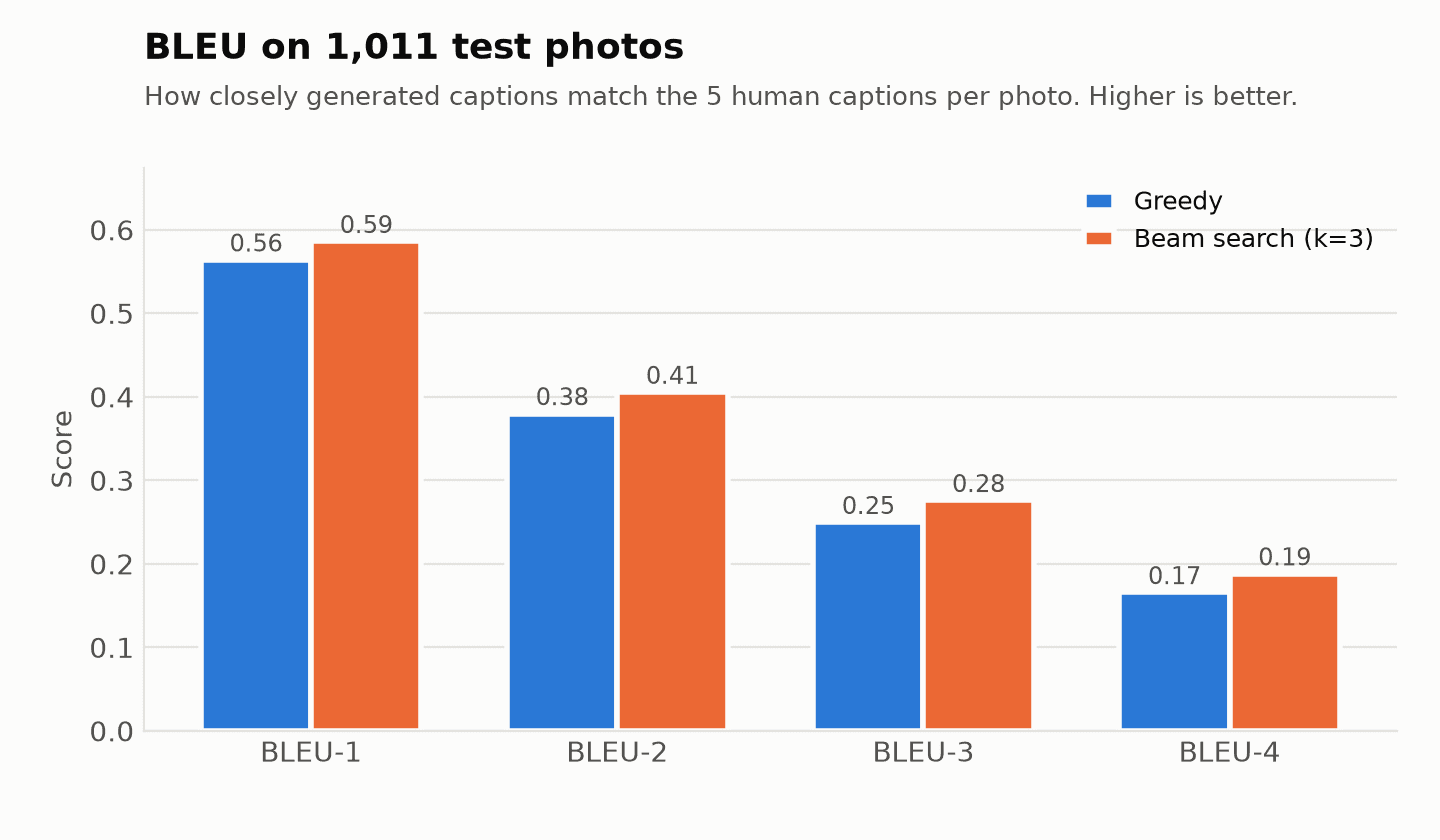
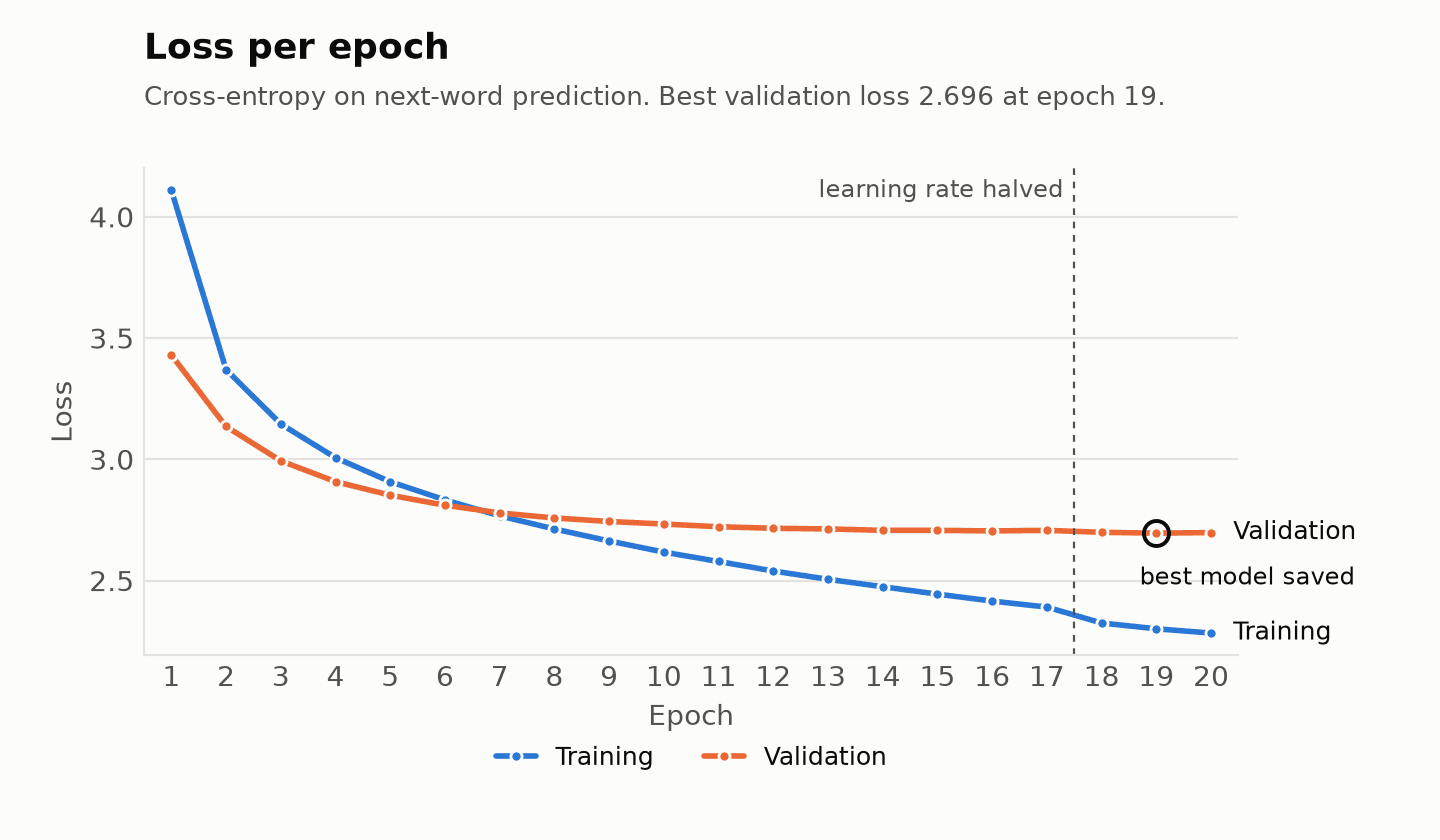
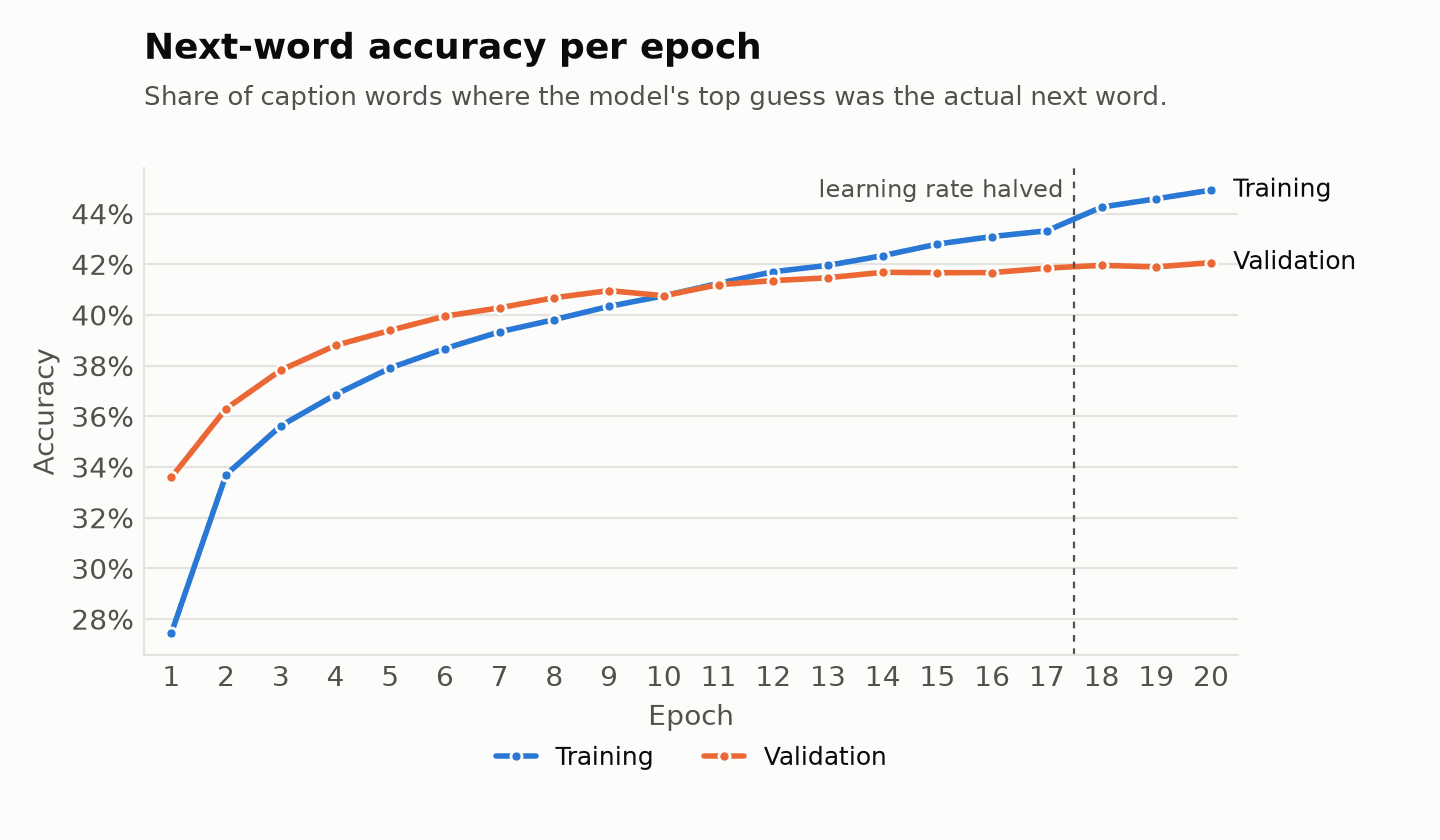
Image Captioning
What is it?
A deep learning model that looks at a photo and writes a natural-language caption for it, one word at a time. A frozen MobileNetV2 encoder extracts image features and an LSTM decoder generates the caption, served through a local Flask demo app.
Objectives
- Combine CNN transfer learning with LSTM sequence generation in one end-to-end model
- Generate grammatically coherent, relevant captions for unseen images
- Evaluate quantitatively with BLEU-1 to BLEU-4 on a held-out test split
- Ship a working upload-and-caption demo app
Outcomes & Contributions
- Built the full pipeline on Flickr8k: caption cleaning, vocabulary, train/val/test splits, and a data generator
- Pre-extracted and cached 1280-d MobileNetV2 features so decoder epochs run without repeating CNN forward passes
- Trained an LSTM(512) decoder with teacher forcing, initialized from the projected image vector, with padding masked out of the loss
- Implemented greedy and beam-search decoding that blocks repeated trigrams and never emits special tokens
- Reached BLEU-4 of 0.188 with beam search (k=3), up from 0.166 with greedy
- Built a Flask app that takes an uploaded image and returns it with the generated caption
Results
| Decoding | BLEU-1 | BLEU-2 | BLEU-3 | BLEU-4 |
|---|---|---|---|---|
| Greedy | 0.564 | 0.380 | 0.250 | 0.166 |
| Beam search (k=3) | 0.585 | 0.406 | 0.276 | 0.188 |
1,011 test images, corpus BLEU against 5 human captions each. Best validation loss 2.696 (epoch 19), ~42% validation next-word accuracy.
- “two dogs are playing in the grass”
- “a black and white dog jumps over a hurdle”
- “a young girl in a pink shirt is playing in a fountain”
Technical Details & Skills
Model
MobileNetV2 Encoder (frozen), Embedding 256, LSTM 512, Dropout 0.5, Adam 1e-3, Teacher Forcing, Beam Search
Data & Evaluation
Flickr8k (8k images, 40k captions), Transfer Learning, BLEU-1 to BLEU-4
Tools
TensorFlow/Keras, NumPy, Pandas, NLTK, Flask
BLEU Scores
Loss per Epoch
Next-Word Accuracy